 Digital Vikingz
What Is Cost of Retrieval?
Cost of retrieval is the compute a search engine spends to crawl, render, segment, extract, and evaluate a page. Higher cost with lower confidence lowers a page's chance of reaching the expensive rerankers. Fewer, cleaner pages cost less to understand.
What is cost of retrieval in search?
Cost of retrieval is the compute a search engine spends to understand a page, from the first fetch to the final evaluation.
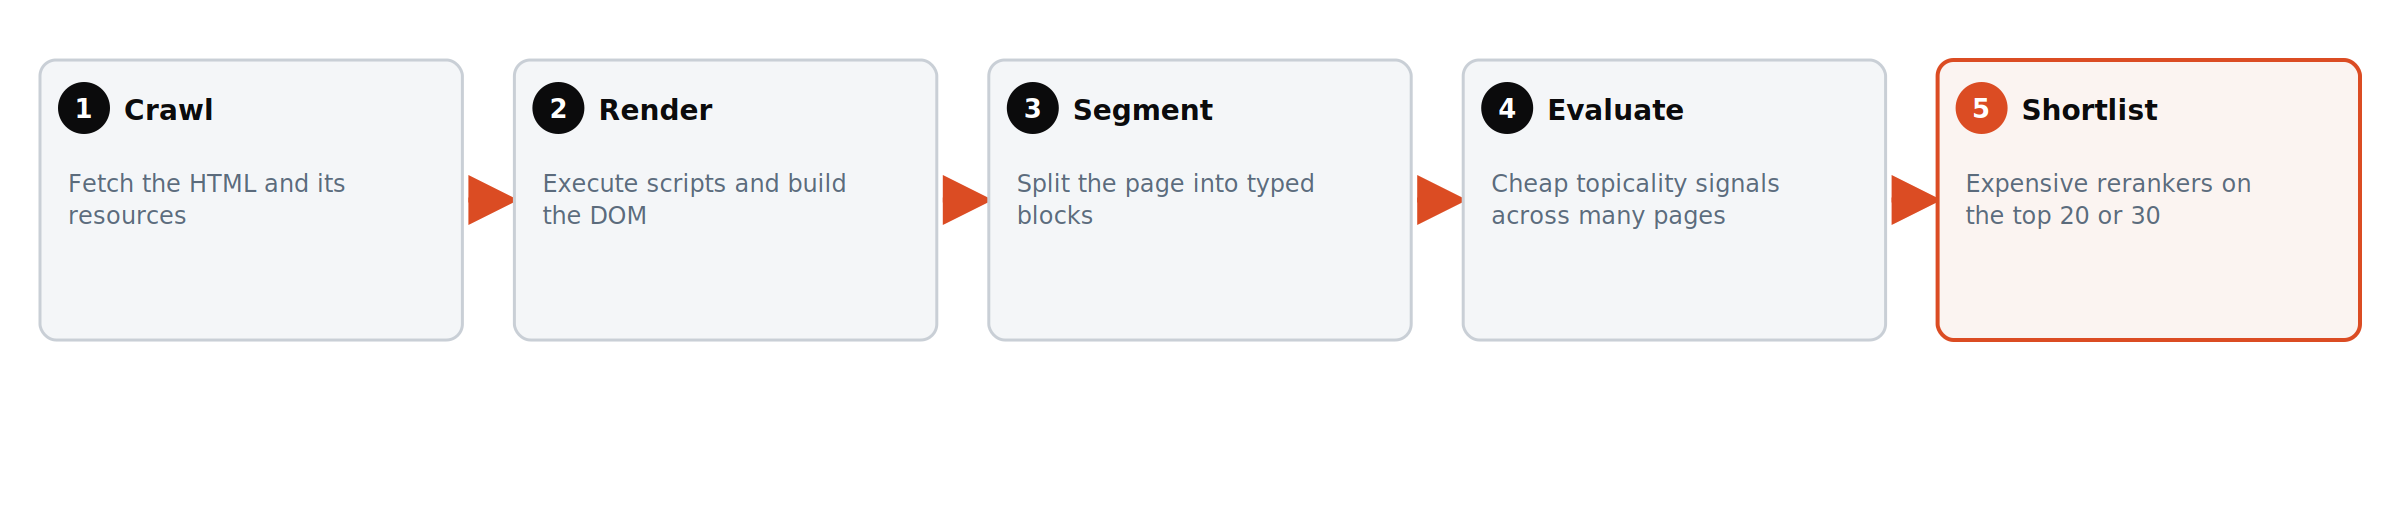
The work runs in stages. The crawler fetches the HTML and its resources. The renderer executes scripts and builds the DOM. The segmenter splits the page into blocks, and the extractor pulls the primary content.
Koray Tuğberk Gübür put cost of retrieval in the denominator of his topical authority formula. The topical authority page covers the full formula. Cost divides everything else a site earns. A site that costs more to understand than its value justifies loses to a cheaper one.
Cost of retrieval is not a term in any published Google document. The verified part is narrower and stronger. Google runs cheap signals on many pages and expensive models on few. Every rule on this page follows from that fact.
How does Google's shortlist turn cost of retrieval into a gate?
Google runs cheap signals on many documents and expensive rerankers on a shortlist, so a page that fails early is never read in depth.
Pandu Nayak's testimony in the DOJ trial describes the funnel. Core topicality signals, PageRank signals, and localization signals take tens of thousands of documents down to a shortlist. Click-based systems miss many documents, because many documents have no clicks. New pages are judged on topicality first.
RankBrain, by the same testimony, looks at the top 20 or 30 documents only. Nayak called it more expensive than some other ranking components. Google waits until the final 20 or 30 before running it. Depth of content matters after that point, not before.
The generative stage is tighter again. Google's filing on its generative search describes summarizing a handful of documents per query, with two or three given as examples. The same filing names saving compute as one reason to return a plain results page. The shortlist for a summary is smaller than the shortlist for reranking.
What do cheap first-pass signals read on a page?
A cheap pass reads the title, the H1, the first characters after the H1, the first blocks, the heading skeleton, and the rendered dimensions.
Those parts cost least to extract. A title written as the query a user types matches on the first read. A heading skeleton that names entities lets passages score without a full reading. A page that hides its entity until the fourth paragraph pays for a deeper read it rarely receives.
Contextless tokens raise cost on every page they touch. Share, Print, Updated, Read time, and Tags inside the content area add words that carry no entity. Across a thousand pages, six stray labels become thousands of tokens of noise. Moving them out of the primary block on the template cleans every page at once.
The Content Warehouse API leak shows Google storing the rendered dimensions and the DOM of a page. Layout shift changes the position of every block below the shift. A stable render gives the same block positions on every read. Stable positions keep the stored representation consistent between crawls.
How do rendering and DOM size raise cost of retrieval?
Every script that builds primary content after load, and every empty node around it, adds work before the page is read.
Primary content belongs in the initial HTML response. Content that appears only after a click, a scroll, or a hover is unsafe for the first pass. Content behind tabs passes when it sits in the DOM on load. Server rendering removes the dependency on script execution.
Render-blocking resources in the head delay everything below them. Third-party scripts, inline SVG bloat, base64 images, and large inline scripts raise file size. Empty spacer divs and placeholder wrappers render as blocks with no content. Google's layout-aware encoder patent names padding as one of its block types.
Deep wrapper nesting adds nodes to resolve. The layout patent reads spatial boundaries rather than DOM depth, so depth is a cost question, not a segmentation rule. Lean markup costs less to parse and render.
How does page count change cost of retrieval?
Page count is a cost, because every URL is crawled, rendered, and evaluated, and pages without a distinct intent add cost without adding coverage.
Google's ranking systems guide states that deduplication hides very similar pages and shows only the most relevant. Two near-duplicates therefore earn one listing at most. The site still pays for the crawl and the evaluation of both. The second page is pure cost.
The same guide states that site diversity generally limits a site to two listings in the top results. A third page on the same query competes with the site's own listings for a cap that does not move. Planning which two pages hold a query is a page-count decision. The rest of the site's pages on that query are overhead.
Query Deserves a Page decides page, section, or sentence for each query variation. Cost of retrieval is the reason that decision matters. Fewer pages concentrate internal links and relevance per document. A dental clinic with one page per treatment and one per real office costs less than one with a page per suburb.
When does pruning lower cost of retrieval?
Pruning lowers cost when a page's intent has no distinct results page type, or when the page sits too close to a sibling.
The audit reads every indexable URL against the live results for its query. A page whose query shows the same page type as a sibling merges into that sibling. A page with no demand and no distinct entity folds into a section. A page that passes stays and gets fixed.
Search Console statuses mark candidates. Crawled, currently not indexed means the engine fetched the page and declined it. Discovered, currently not indexed means the engine knows the URL and has not crawled it yet. Reading both as quality signals is consistent with Google's own guidance on those statuses.
Merges redirect to the surviving page, and that page absorbs anything unique from the merged one. Programmatic sites test the change on a sample page group first. One structural change ships per cycle. A recrawl spike follows a site-wide change, and judgment waits for a full crawl cycle after it.
- Koray Tuğberk Gübür, Search Engine Land: Visual semantics, the missing piece of topical authority
- Google Search Central: A guide to Google Search ranking systems
- US 2024/0289407 A1: Search with stateful chat (Google, pending application)
- US 12,393,768: Layout-aware multimodal pretraining for multimodal document understanding (Google)
Patents and filings describe systems Google has invented. None is a confirmed ranking factor.
What should you read after cost of retrieval?
 What is topical authorityTopical authority is a site's standing on a topic, as a search engine judges it.
 Query Deserves a PageQuery Deserves a Page is the test that decides if a query variation gets its own page, a section, or a sentence.
 What is centerpiece annotationCenterpiece annotation is Google's label for the primary content block of a page, extracted from its HTML structure.
 Visual semanticsVisual semantics is the meaning a search engine reads from a page's layout, blocks, and components alongside its text.
 Semantic Content AuditSix checks. Each one has a defined failure and a defined fix.
 Website DevelopmentFive platforms, chosen by what the architecture needs, not by preference.
 Talk to usMessage the team on WhatsApp
Questions about cost of retrieval
Is cost of retrieval the same as page speed?
Is there a size limit for a page's HTML?
Does a large site automatically carry a high cost of retrieval?
How is cost of retrieval measured?
Does moving a section to a subdomain lower cost of retrieval?
Does cost of retrieval matter for a single-page site?
Which platform has the lowest cost of retrieval?
Does removing pages hurt topical coverage?
Does longer content raise cost of retrieval?
How often is cost of retrieval reviewed?
Who fixes cost of retrieval issues, SEO or development?
See it applied to your site
The Semantic Content Audit uses every term in the knowledge hub. Fixed scope, written deliverable.