 Digital Vikingz
What Are Author and Organization Entities?
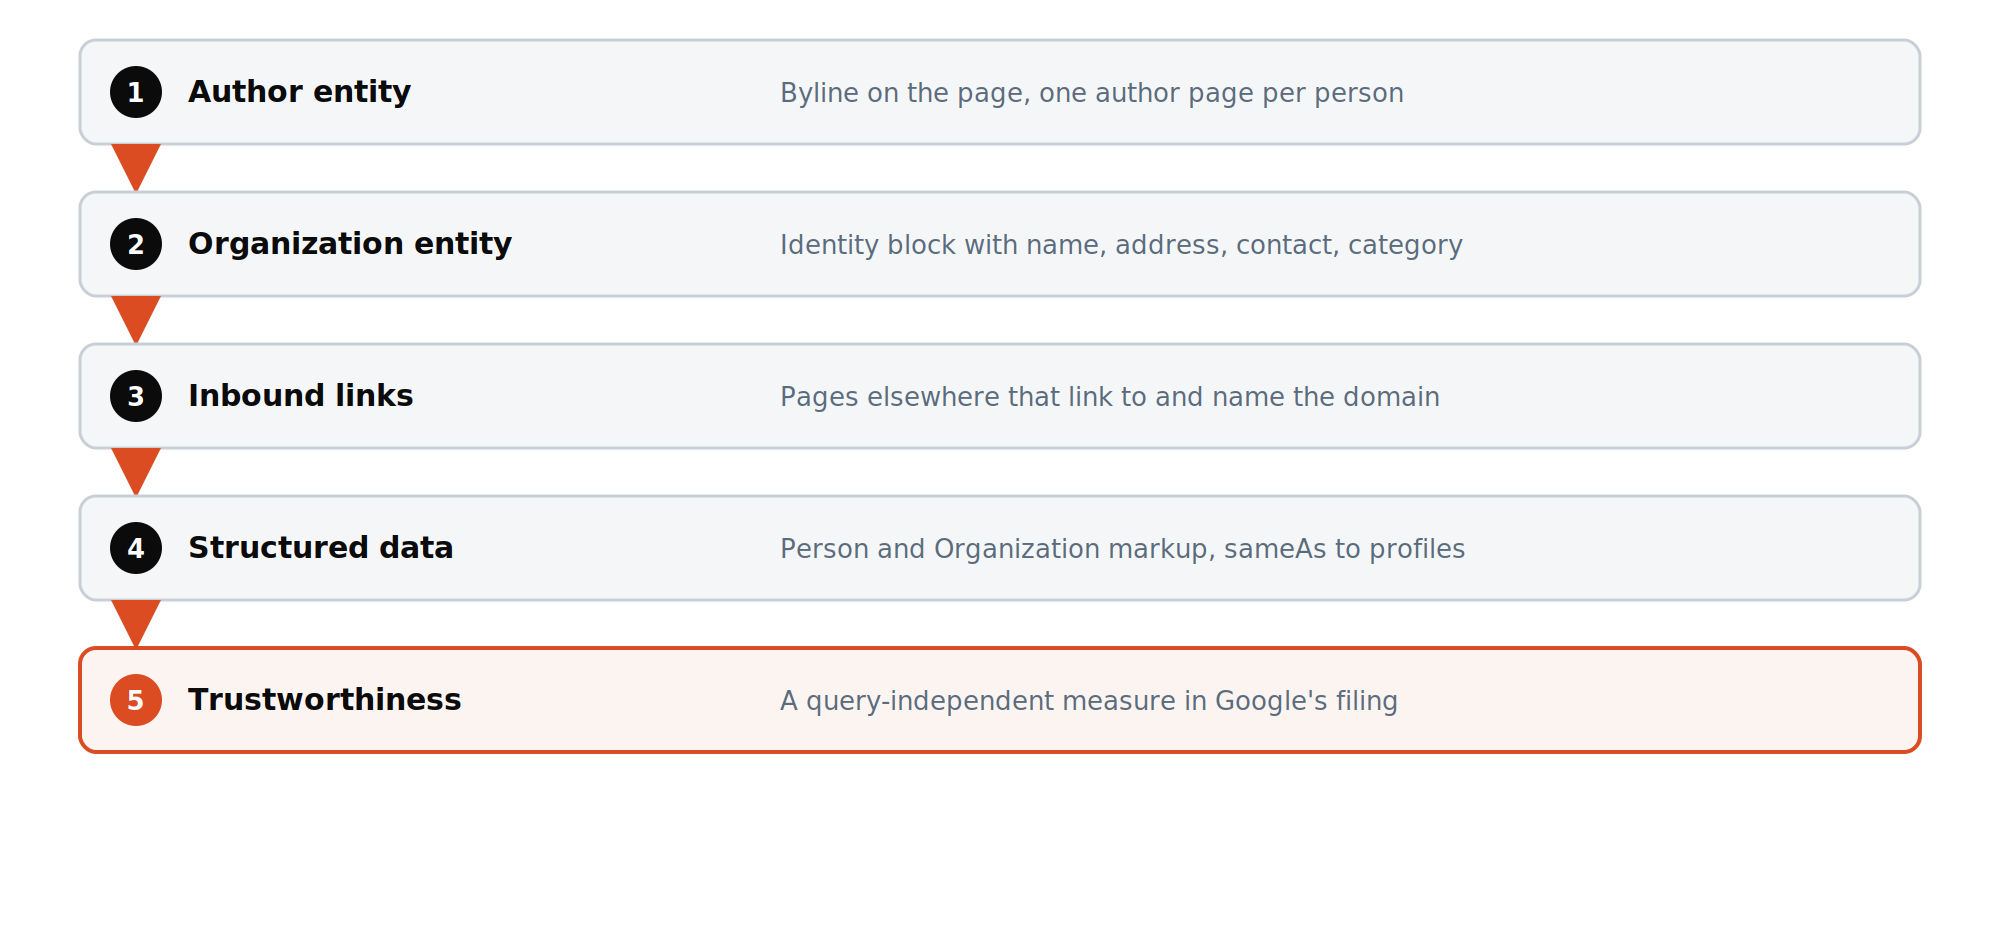
Author and organization entities are the named person and the named business a page declares as responsible for it. Google's generative search filing reads trustworthiness from author, domain, and inbound links. A byline, an author page, an identity block, and matching structured data make those inputs resolvable.
Which trust inputs does Google's generative search filing name?
Google's generative search filing names three sources of trustworthiness for a document: its author, its domain, and its inbound links.
The filing is US 2024/0289407, still pending. Trustworthiness sits among its query-independent measures, next to selection rate across queries, overall popularity, and freshness. The measure helps select the handful of documents a summary is built from. The filing also weighs verifying documents by trustworthiness when it rates confidence in a summary sentence.
The filing does not say how author or domain trust is computed. The page-side reading is plain: a page names its author, the author resolves to a profile, and the domain resolves to an organization. Anonymous pages have one fewer trust input. The agency builds to that reading and does not sell it as a ranking factor.
Source trust appears in the older query augmentation patent too. The patent scored synthetic queries higher when they came from sources with configuration control, such as established companies, directories, and government repositories. Blogs and community pages scored lower. The patent has lapsed, so the point is design logic, not a guarantee.
What does Google's helpful content guidance say about who, how, and why?
Google's helpful content guidance asks three questions of every page: who created it, how it was created, and why it exists.
Who asks if authorship is self-evident to visitors. Google points to bylines and background information about the author. How asks for background on the process, including how automation or AI generation was used. A product review answers how with the number of products tested, the results, and the test method.
Why is the question Google calls perhaps the most important. Content exists primarily to help people, not to attract search visits. Google adds that E-E-A-T itself is not a specific ranking factor. Its systems use a mix of signals to identify content that shows those qualities, and trust counts most.
Google's rater guidelines ask raters to find who is responsible for a website and who created the content on a page. Rater scores evaluate search results; they do not rank pages directly. The reviews system in Google's ranking guide rewards reviews with expert or enthusiast authorship. Topics that affect health, finances, or safety get more weight on strong E-E-A-T.
What does an author entity need on the page and on the author page?
An author entity needs a linked byline on the page and an author page that states who the person is.
The byline names the person the same way on every page. The link goes to one author page per person, never to a search results page or a social profile. The author page states the name, the role, the credentials, and the specialism. The author page also lists the pages the person wrote or reviewed. A pen name with no profile gives a system nothing to resolve.
The byline sits outside the primary content in DOM order. A byline, a date stamp, or a share bar between the H1 and the first body block lands inside the centerpiece Google extracts. The name then reads as part of the page's opening passage. Centerpiece annotation covers that failure in detail.
Digital Vikingz follows the pattern on its own site. Every article closes with a band naming Usman Ishaq as writer, with his role, his certification, and a review date. The band links to his profile on the team page. The name and the profile link match the Person entry in the page's structured data.
What belongs in an organization identity block?
An organization identity block holds the business name, address, contact details, and category as visible text, reachable in one click from every page.
The block uses one canonical business name. Brand and organization names are strings the lapsed augmentation patent did not transform, so a second spelling is a second string. The address, phone, and category match the site's directory listings token for token. Local businesses carry the same block on the homepage and on each location page.
The block lives in a stable place: the footer, the contact page, or the team page. Every page reaches it in one click. The site name Google shows in results is a separate, documented feature, set with WebSite structured data. The site name, the identity block, and the Organization markup use one string.
The block states facts, not claims. Awards, client logos, and review stars belong elsewhere on the page. A block crowded with badges reads as promotion, and the name and address lose their place as its subject. Each line holds one attribute of the organization: name, address, phone, email, or category.
How do Person and Organization structured data connect a site to its entities?
Person and Organization structured data restate the visible identity in schema.org types, and sameAs links each entity to pages that describe it.
Person markup carries name, url, jobTitle, and worksFor, which points to the Organization. Organization markup carries name, url, logo, address, and contactPoint. Each article's author property points to the Person, and its publisher property points to the Organization. The graph in the markup then matches the graph in the visible text.
Schema.org defines sameAs as the URL of a reference page that identifies the item. A name alone is ambiguous, because many people share a name. The sameAs links connect the name to pages that already describe one specific person or business. Each link narrows the name to one entity.
Markup restates; it does not create. A page with Person markup and no visible byline declares an author the reader never sees. The agency rule is that every property in the markup appears in the visible text of the page or the linked profile. Mismatched names across markup, byline, and listings split one entity into several strings.
- Google Search Central: Creating helpful, reliable, people-first content
- Google: Search Quality Rater Guidelines (PDF)
- US 2024/0289407 A1: Search with stateful chat (Google, pending application)
- Google Search Central: A guide to Google Search ranking systems
- US 9,916,366 B1: Query augmentation (Google, expired)
Patents and filings describe systems Google has invented. None is a confirmed ranking factor.
What should you read after author and organization entities?
 AI citation readinessAI citation readiness is the degree to which each sentence on a page verifies a sentence in a generative summary.
 What is centerpiece annotationCenterpiece annotation is Google's label for the primary content block of a page, extracted from its HTML structure.
 What is a central entityA central entity is the one entity a website is about, defined in a single sentence that every page inherits.
 Query augmentationQuery augmentation is the expansion of a search query into related phrasings, entity types, attributes, and contexts bef.
 AI Search VisibilitySix requirements, each tied to a stage in the pipeline. Each one is tested before and after.
 Authority SignalsA placement is made only when all five pass. The report shows the pass record for each one.
 Talk to usMessage the team on WhatsApp
Questions about author and organization entities
Does every page need a named author, including service pages?
Can a company publish under its organization name instead of a person?
Does disclosing AI assistance hurt a page?
Which credentials belong on an author page?
Should guest authors get author pages?
What happens to an author page when the author leaves?
Is a Google Business Profile part of the organization identity?
What is a reviewed-by line, and when does a page carry one?
Which profiles belong in sameAs?
Does an author's reputation off the site matter?
How does a company with several brands mark up its organizations?
Do author pages need their own structured data?
See it applied to your site
The Semantic Content Audit uses every term in the knowledge hub. Fixed scope, written deliverable.